Six live projects, an audited ground truth, and full agentic conditions – an addendum to our January system card.
In January we published our early Matrak Connect results – benchmarking 5 of our AI Agents against human workers in real-world, commercially valuable, construction tasks. The results were overwhelming, so thank you to everyone who joined or asked to join our early access program – your wait is almost over!
We’re closing the final reviews ahead of our public agent launch, so it’s a perfect time to review where the system currently stands – particularly given some wild AI developments over the past month.
Today, I’m excited to share new benchmarks for our first publicly available Matrak Connect Agent – our AI Takeoff and Estimation system – comparing against 5 frontier models, including fully-agentic Fable 5 and ChatGPT 5.6 Sol.
The full report
Matrak Connect AI Takeoff: System Card Addendum
Six live projects, an audited ground truth, and full agentic conditions – the complete methodology, per-project results and every model condition.
Previously:
the January system card (full paper, PDF)
·
the original announcement (blog post)
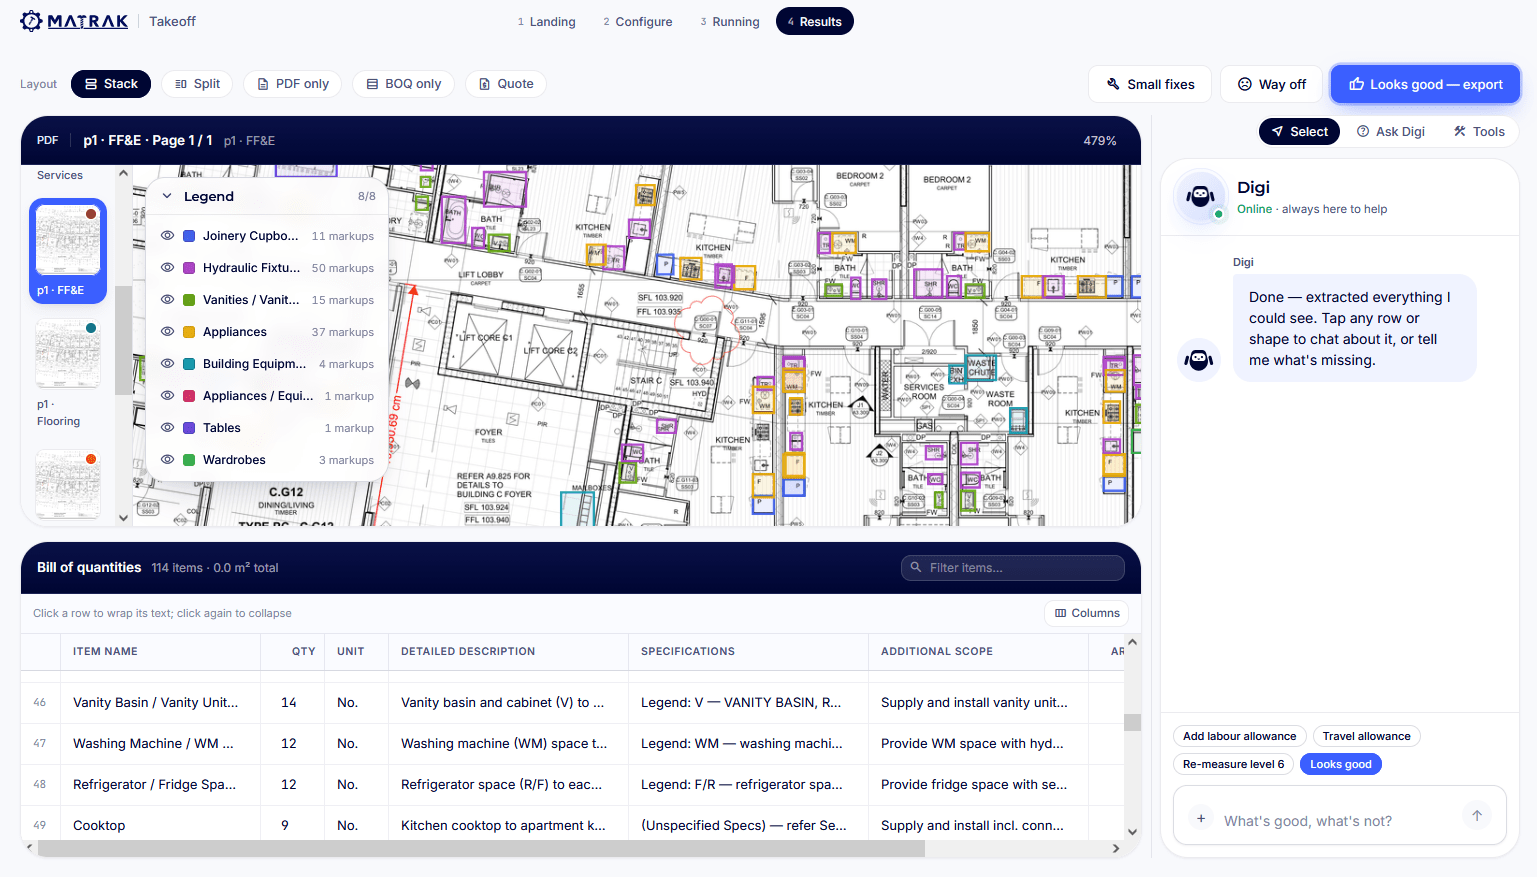
AI Takeoff Background: Any time a supplier, manufacturer, builder or installer tenders for a job, they need to perform a ‘takeoff’ – counting and measuring every product from the 2D drawings. This takes days or weeks, and needs to be repeated by every tendering subcontractor – comfortably many hundreds to > 1000 companies performing this activity for a single major project. The economic cost is huge – over 500K full-time roles dedicated to this in AU, UK and US alone, with a long-tail approaching 1M in those 3 markets when part-time and outsourced estimators are included. It’s a boring, high-stakes activity with limited benefit – the takeoff is the work that allows you to bid for a job, it doesn’t guarantee you’ll win it or get paid for the labour. It’s also the #1 requested AI Agent in our Matrak Connect family, and will be the first one to launch publicly in the coming weeks.
Numbers first then the breakdown:
Figure 1.
Mean Output Usability across six projects (% of quote lines an estimator could use as-is), scored against the audited ground truth. Only Matrak Connect clears the partner-set 85% threshold.
So what are we looking at?
In collaboration with one of our early-access partners (a major multi-national supplier), we worked with their human estimating team to develop a pool of 6 live construction projects, with granular step-by-step working, to go from raw drawings to a final fully-spec’d quote for submission.
We know that takeoff is often inexact and difficult to verify. So we had a 2nd team of human estimators ‘red team’ the results, using AI Auditors to reconcile errors. Both teams found issues with each other’s work, and we only considered the benchmark ready when we had line-by-line consensus from all parties.
This red-teaming surfaced something we knew anecdotally already – in the typical time constrained environment, errors slip into even experienced estimators’ work. We found that the experienced human estimator only hit around 66% accuracy compared with our audited benchmark across the 6 projects. We consider this to be a realistic floor of experienced human performance rather than a ceiling, and commercial businesses have a number of layers (QA, client review etc) designed to mitigate these errors. But it’s still a very telling demonstration of the difficulty of the task.
Our Matrak Connect AI Takeoff Agent was significantly above all other benchmarks, including the human estimator, sitting at 89% accuracy. The agent builds on our patented method for materials extraction, giving it access to tools and techniques beyond what current LLMs can deliver. This comfortably puts it in the usability zone for autonomous takeoff.
Fable 5 running fully agentically was a big step up at 64% accuracy – however it’s important to note that Fable’s errors were heavily focussed on overcounting (i.e. ordering 2 products instead of one), where the human erred in undercounting. Undercounting is much commercially safer – in construction there’s many more opportunities to order additional goods without risking the project, where an over-order is immediately costly. This is why it fell below the “Commercial Usability Threshold” of 85% – the errors are common enough and severe enough that a human estimator would need to perform granular QA before using these results – which negates the benefit of automation, as it would then be faster for the estimator to do it themselves.
Figure 4.
Direction of quantity error, pooled over six projects (line counts). The human under-counts (the quiet, recoverable error); the frontier model over-counts (the expensive one). Matrak’s errors are both fewer and close to balanced.
Full methodology, the audited ground truth, per-project results and every model condition are documented in the addendum → read the full addendum.
The surprises
- Gemini Flash 3.5 absolutely overperformed – as a mid-tier, lightweight model, it performed significantly higher (and significantly cheaper) than the latest OpenAI release and Anthropic’s Opus 4.8.
- ChatGPT 5.6 Sol was a huge surprise. Even on High, and in full Agentic mode, it was significantly below smaller/older models.
- Chat vs Agentic had a smaller delta than we’d expect. Agents had full access to code execution, local hdd, tool use etc. While there was definite uplift, it wasn’t the night-and-day improvement we’d anticipated.
I should state the obvious that performance on a hyper-niche private trade benchmark does not predict how these models will perform for other benchmarks or use-cases – all indications are that ChatGPT 5.6 is at or near the pinnacle of performance across many areas. But it’s an interesting reflection of the “spiky” nature of LLM intelligence, that this particular task – with its spatial reasoning, long context, and multi-modal requirements – provides quite a different lens to other public benchmarks.
Where to next?
We’re in the final stages of beta testing for the AI Takeoff Agent. If you’d like access, head to matrak.com/matrak-connect and register your interest.
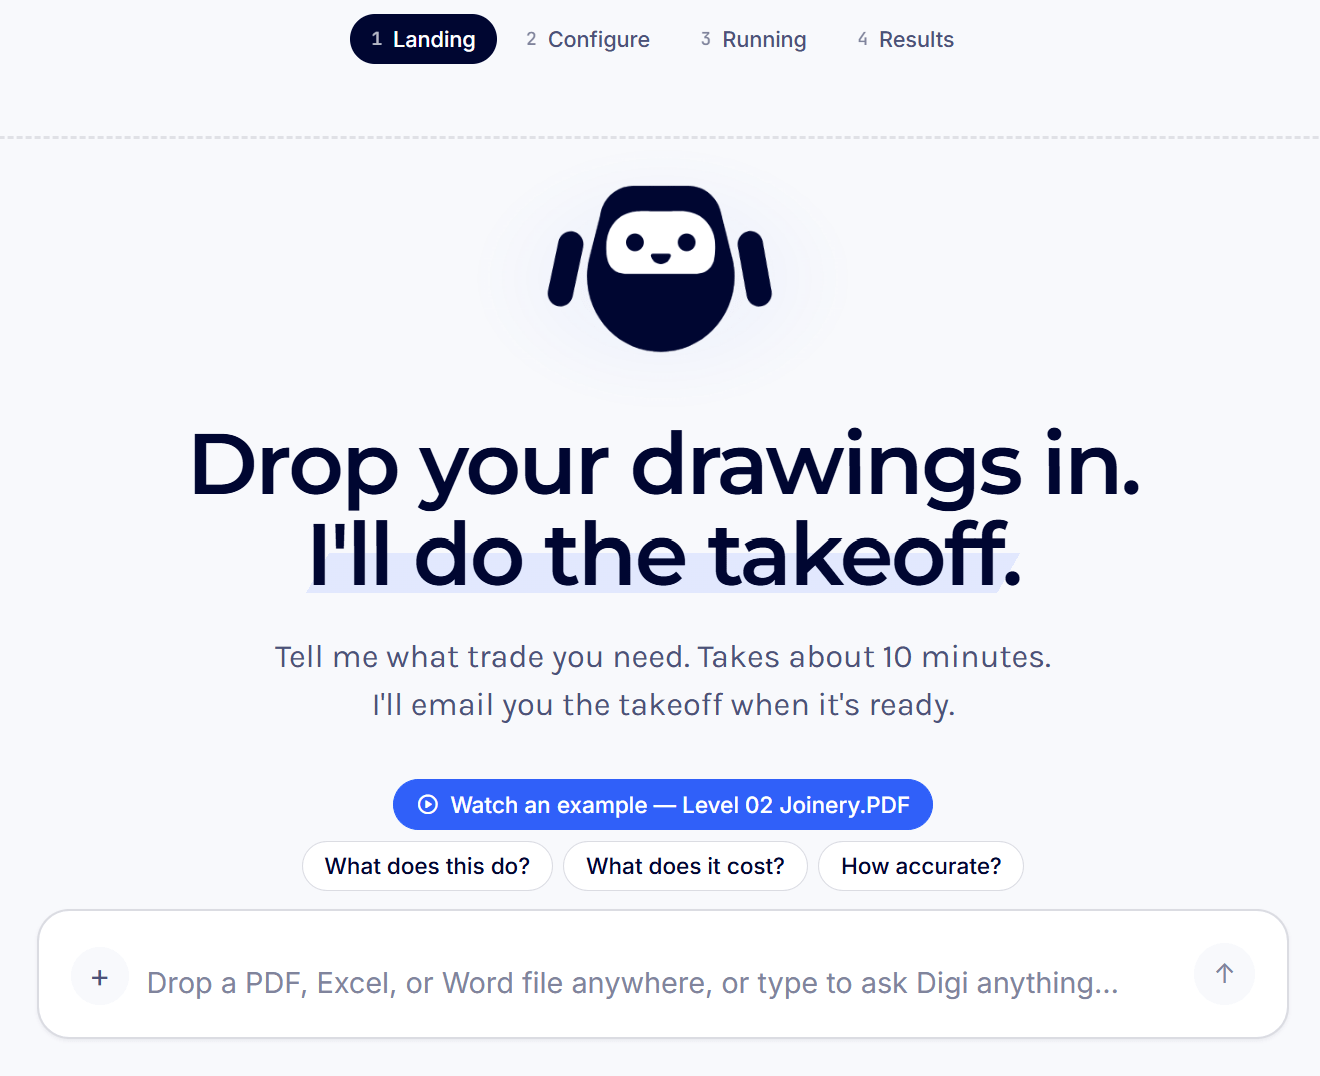
Takeoff is one of the most thankless, monotonous and unrewarding tasks in construction. Every single customer we’ve spoken to is chomping at the bit to put this task to bed – and get their weekends back, while giving more time to focus on quality, sustainable construction. We’re excited to be part of this story, and absolutely cannot wait to share more at our upcoming launch.